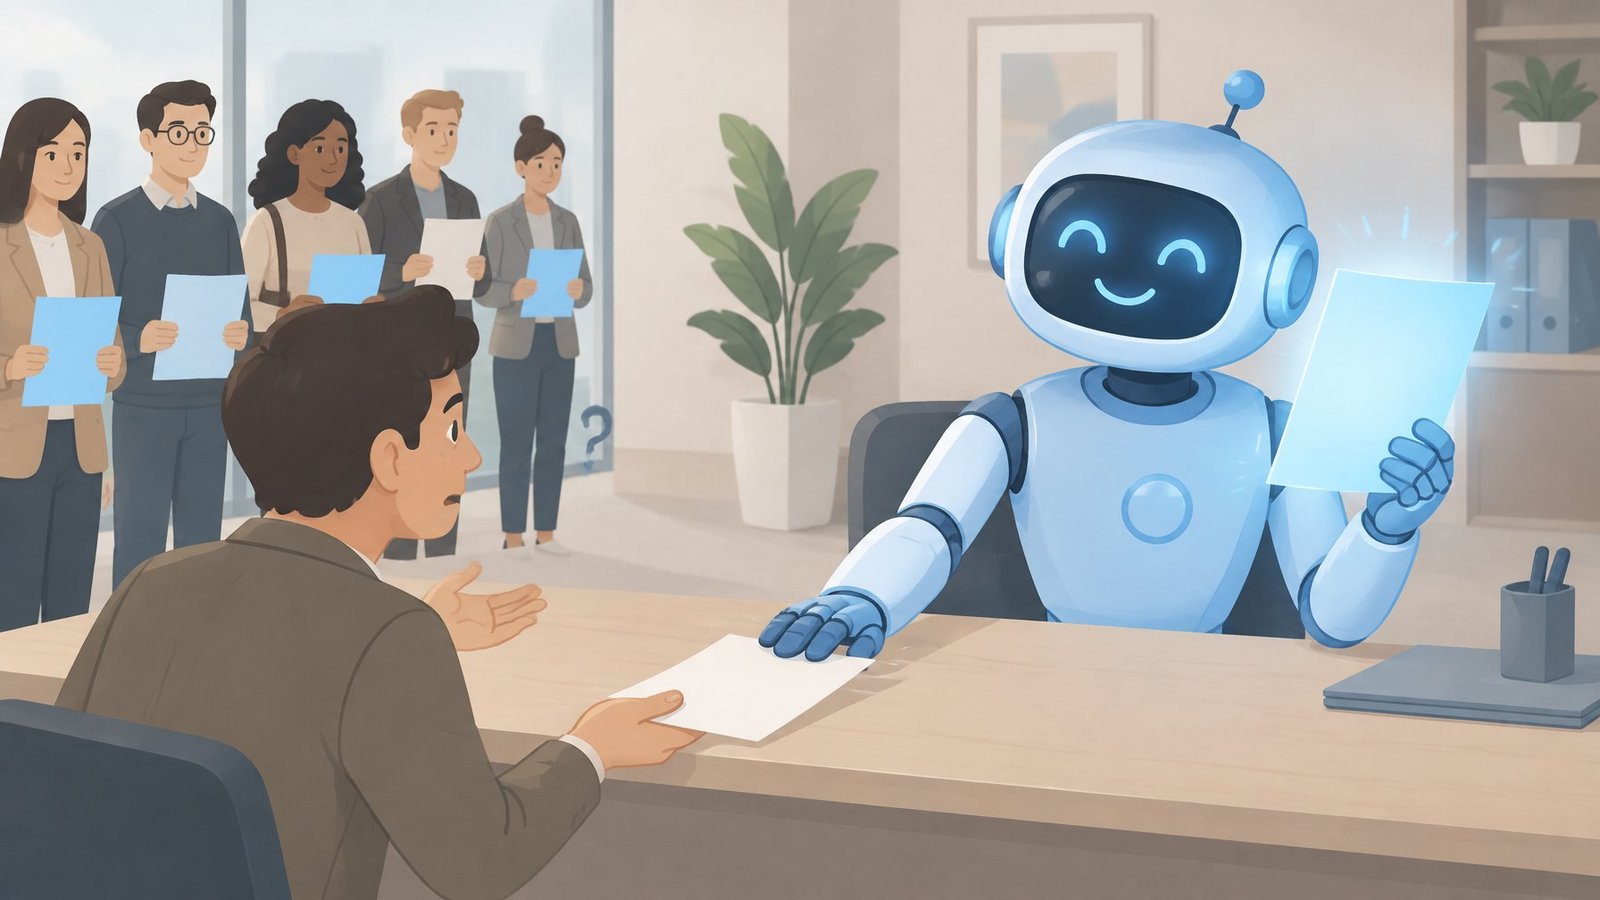
Job seekers who polish their resumes with an AI model may get an edge when an employer screens them with the same model. A large experiment found that language models consistently pick resumes they wrote themselves over human-written versions describing the same candidate.
The study is by Jiannan Xu of the University of Maryland’s Robert H. Smith School of Business, Gujie Li of the National University of Singapore and Jane Yi Jiang of Ohio State University’s Fisher College of Business. It was first posted on arXiv on August 30, 2025, and revised on June 6, 2026.
Same candidate, different author
The researchers started from 2,245 anonymized resumes written by real job seekers on the LiveCareer platform before generative AI was widespread. The resumes spanned 24 occupations, from teachers and chefs to engineers and consultants.
They focused on the executive summary, the short free-text pitch at the top of a resume. For each resume, several models wrote a new summary for the same person, using the full resume, while education, experience and skills stayed untouched. Models tested included GPT-4o, GPT-4o-mini, GPT-4-turbo, LLaMA 3.3-70B, Mistral-7B, Qwen 2.5-72B and DeepSeek-V3.
Each model then acted as a screener and was shown two summaries for the same candidate: one it had written and one written by a human or by another model. The order was randomized to cancel out any preference for the first or second option.
A strong pull toward their own text
Eight of the nine models in the main comparison favoured their own summaries over the human originals, by margins of 26% to 98% on a raw measure. GPT-4o picked its own version 97.6% more often than the human one, while the smallest LLaMA model showed no such preference.
Better writing does not explain it all. Using a second measure that accounts for content quality, the bias against human-written resumes still ranged from 67% to 82% across major commercial and open-source models, and the authors report that larger models showed stronger self-preference.
Model-versus-model bias was patchier. DeepSeek-V3 preferred its own output by 69% against LLaMA 3.3-70B and by 28% against GPT-4o, while GPT-4o and LLaMA 3.3-70B did not consistently favour themselves over other models.
What it means for applicants
To estimate the real-world stakes, the team simulated hiring pipelines across all 24 occupations. Candidates who used the same model as the screener were 23% to 60% more likely to be shortlisted than equally qualified applicants with human-written resumes. The gap was largest in business fields such as accounting, sales and finance, and smallest in areas like agriculture, arts and automotive.
The authors warn that repeated hiring rounds could produce a “lock-in” effect, in which the style favoured by dominant models becomes entrenched in applicant pools.
They also tested two cheap fixes. One instructed the screening model to ignore where a resume came from and judge only its content. The other combined the screener with smaller models that are worse at recognising their own writing and took a majority vote. Across the models tested, these steps cut the bias against human-written resumes by 17% to 63% in relative terms.
Study Details:
- Title: AI Self-preferencing in Algorithmic Hiring: Empirical Evidence and Insights
- Authors: Jiannan Xu, Gujie Li, Jane Yi Jiang
- Journal: arXiv preprint 2509.00462
- Publication Date: August 30, 2025
- Link: https://arxiv.org/abs/2509.00462